Crawl4AI for AI Agents: Web Data Extraction Guide
Crawl4AI for AI Agents provides a practical bridge between autonomous AI systems and live web content. An AI agent may
Crawl4AI for AI Agents provides a practical bridge between autonomous AI systems and live web content. An AI agent may
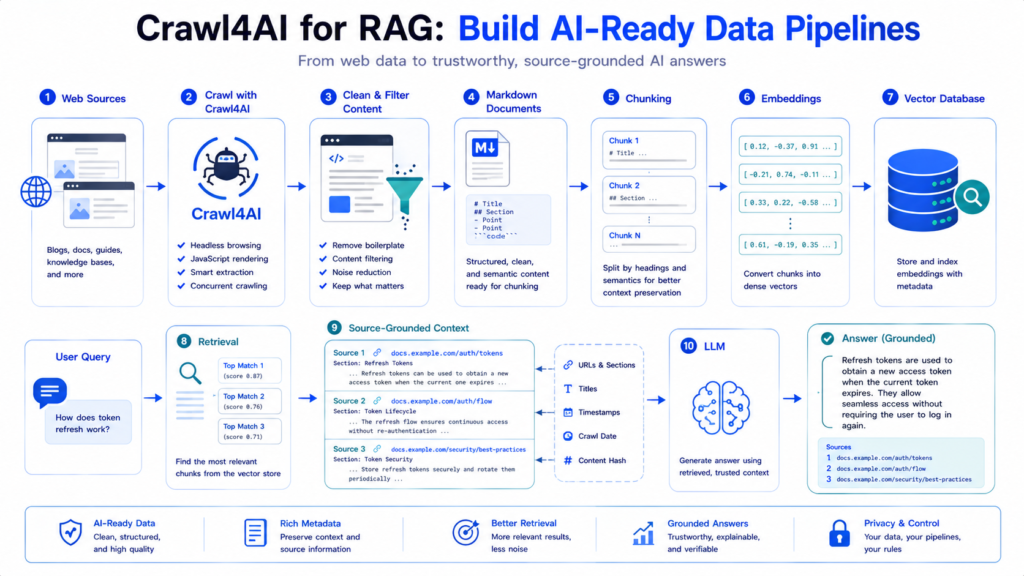
Crawl4AI for RAG connects web crawling with retrieval-augmented generation by turning live webpages into cleaner, structured content that can be
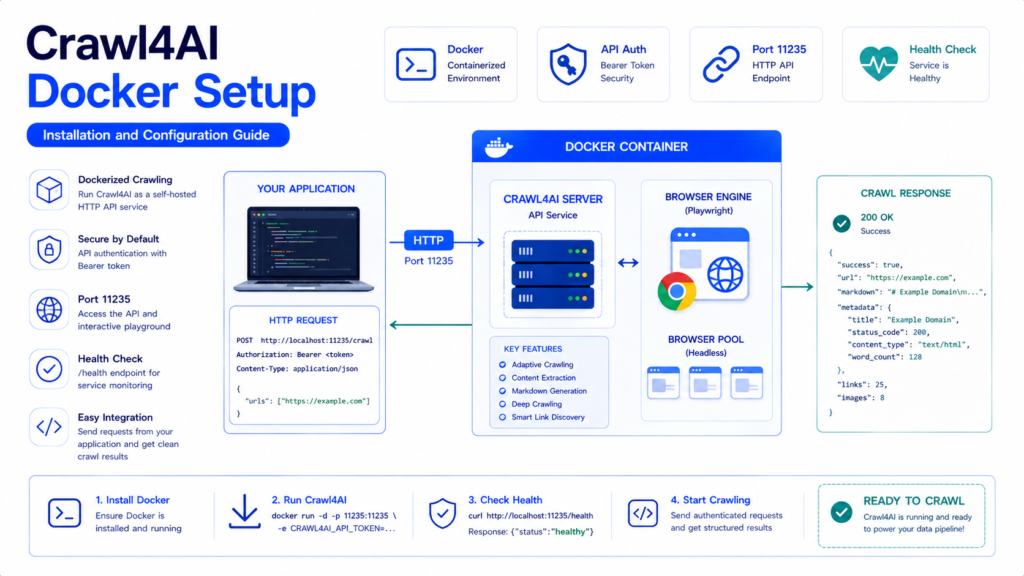
Crawl4AI Docker Setup provides a practical way to run Crawl4AI as a self-hosted HTTP service instead of installing and managing
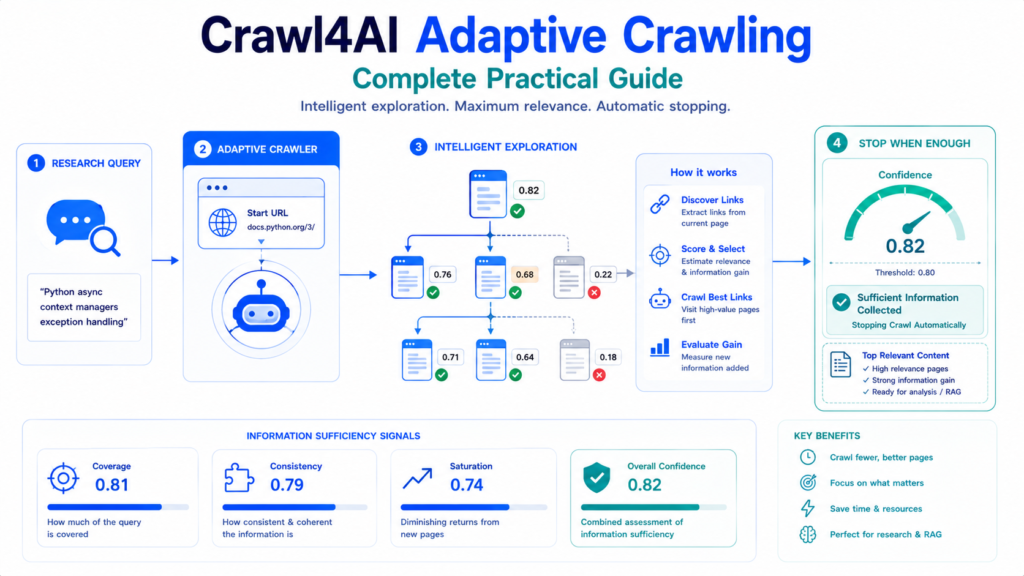
Crawl4AI Adaptive Crawling changes multi-page crawling from a fixed traversal problem into an information-sufficiency problem. Instead of deciding in advance
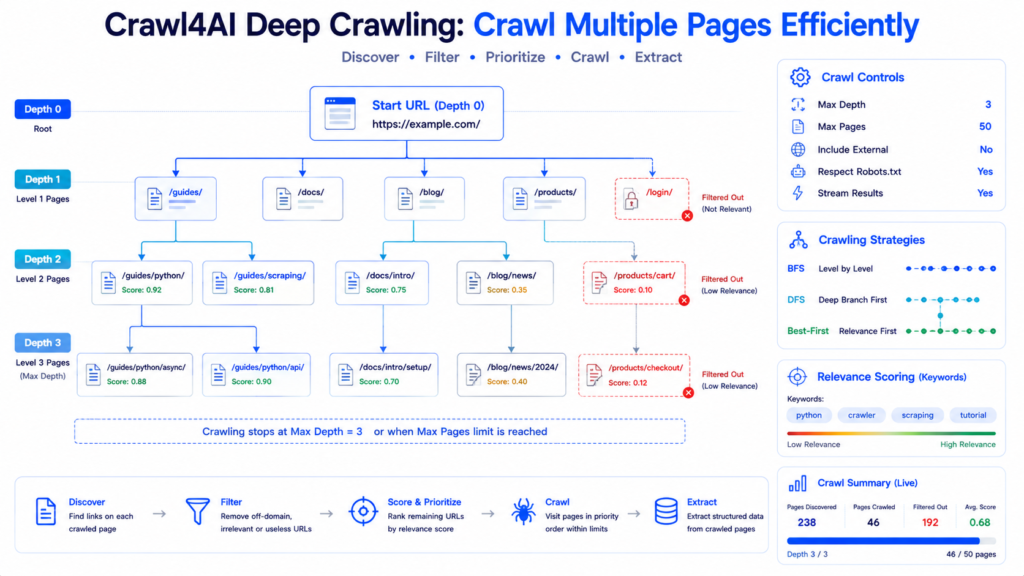
Crawl4AI deep crawling lets developers move beyond extracting a single URL and systematically explore linked pages across a website. A
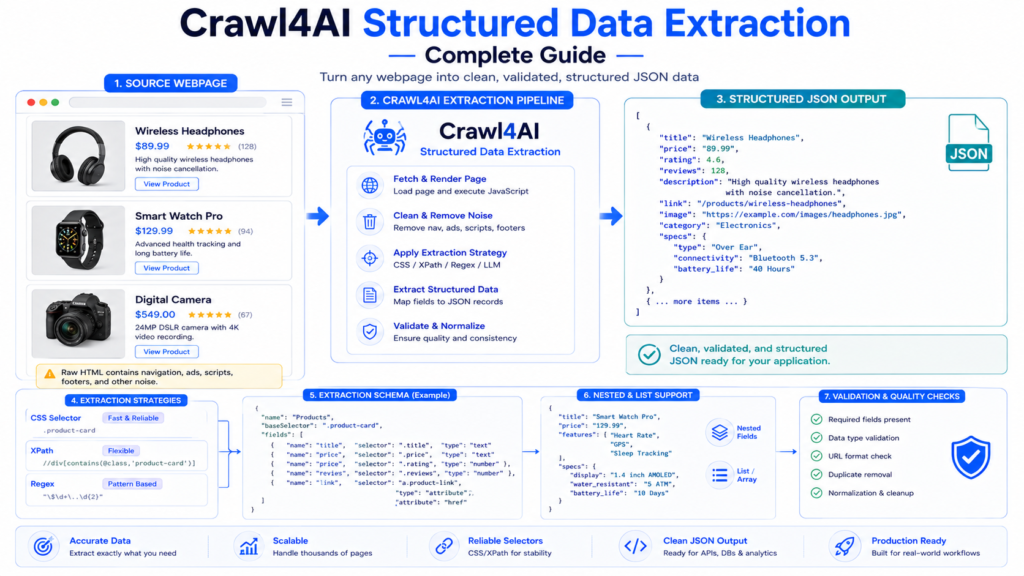
Crawl4AI structured data extraction turns webpage elements into predictable records that applications can process directly. Instead of returning an entire
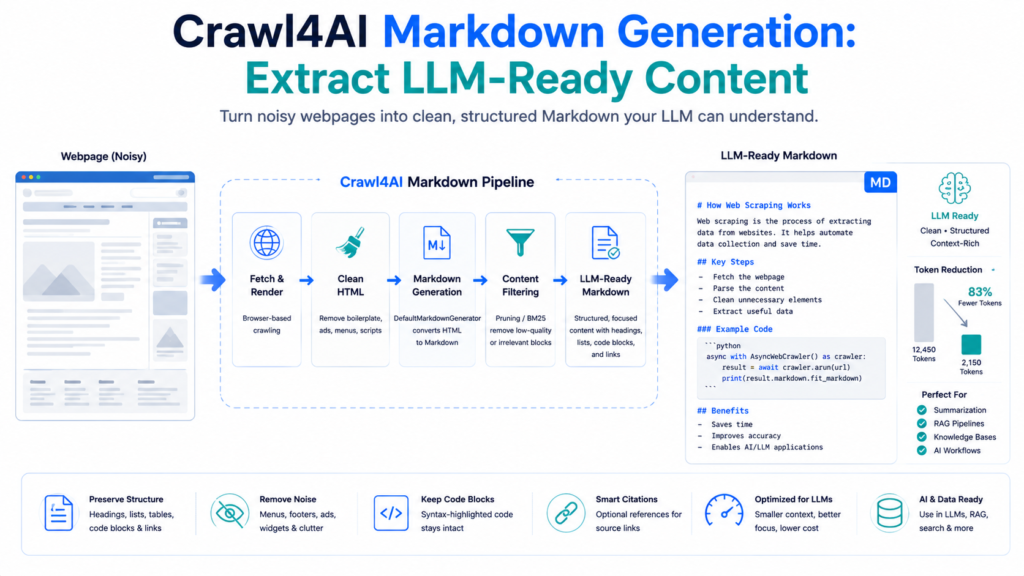
Crawl4AI Markdown generation converts complex webpage HTML into structured, readable content that is easier to use in LLMs, knowledge bases,
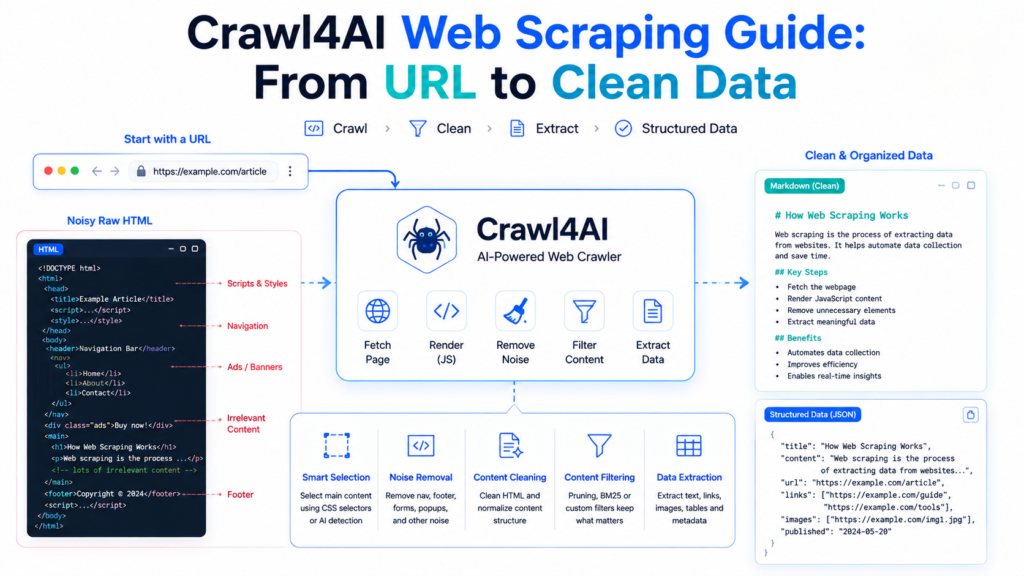
Crawl4AI turns a webpage URL into cleaner, more useful data by combining browser-based crawling with content selection, HTML cleanup, Markdown
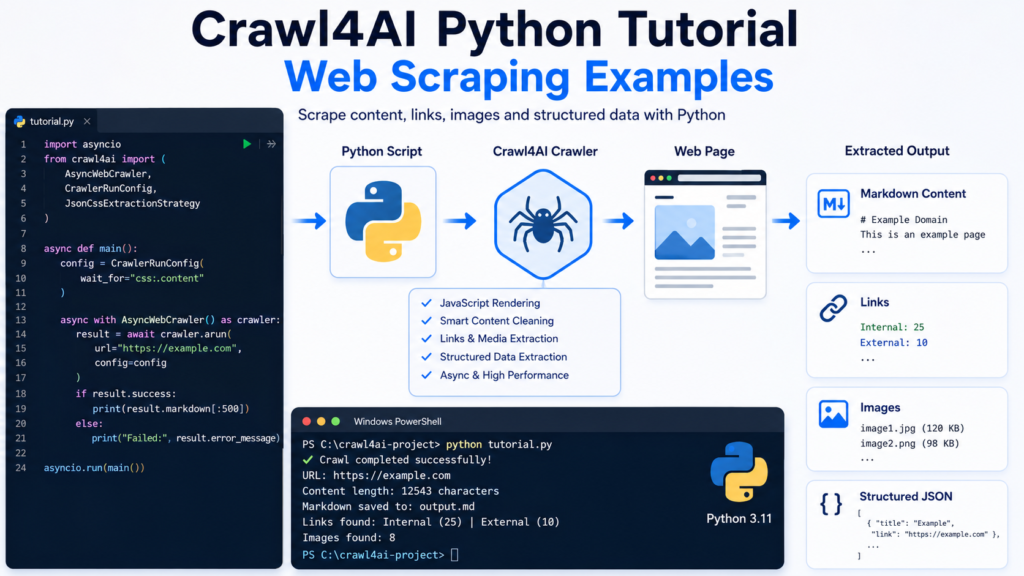
Crawl4AI gives Python developers a practical way to turn webpages into usable content without manually handling every browser, parsing, and
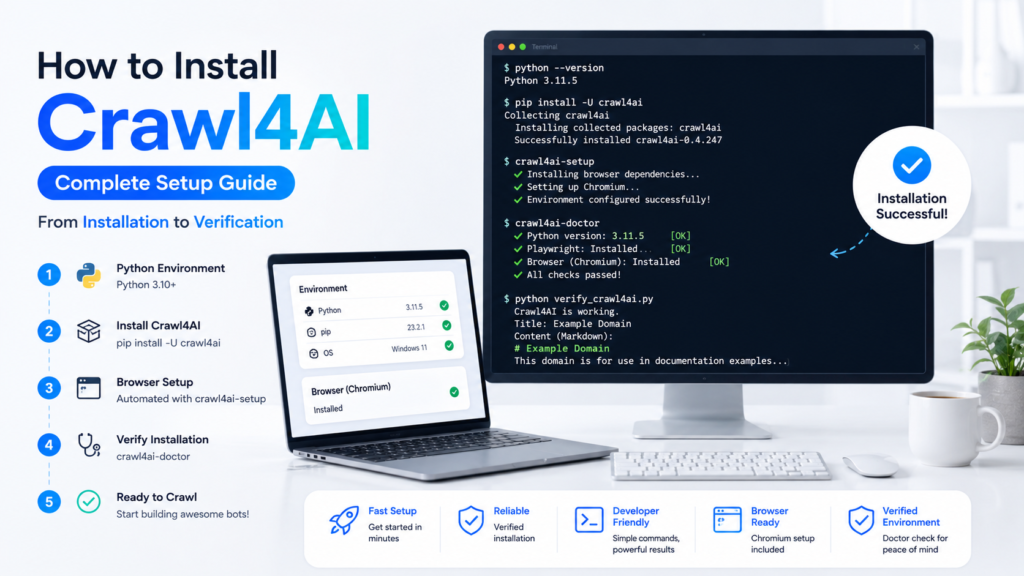
Crawl4AI installation starts with a compatible Python environment, followed by the package installation and browser setup required for web crawling.