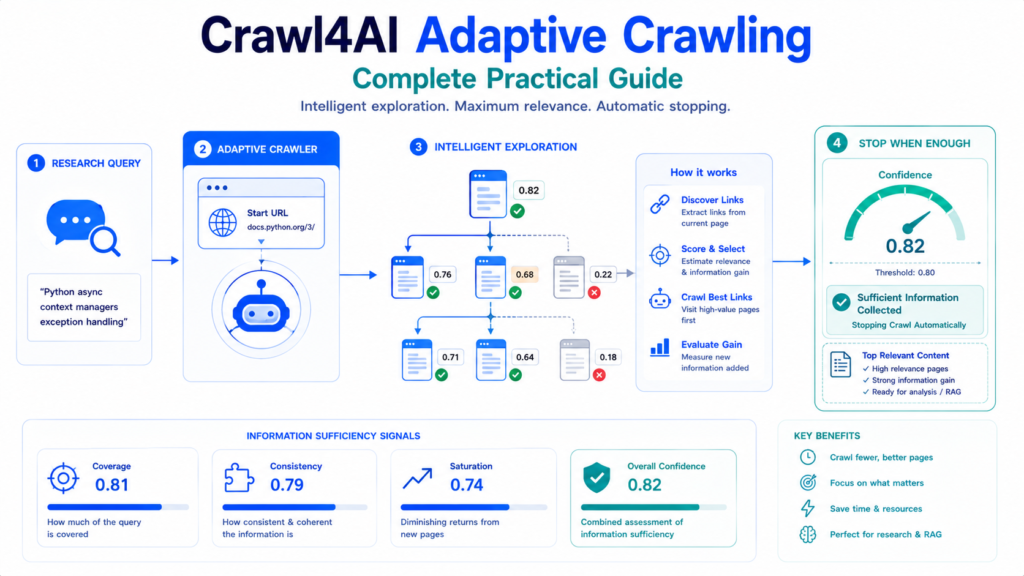
Crawl4AI Adaptive Crawling: Complete Practical Guide
Crawl4AI Adaptive Crawling changes multi-page crawling from a fixed traversal problem into an information-sufficiency problem. Instead of deciding in advance
Crawl4AI Adaptive Crawling changes multi-page crawling from a fixed traversal problem into an information-sufficiency problem. Instead of deciding in advance
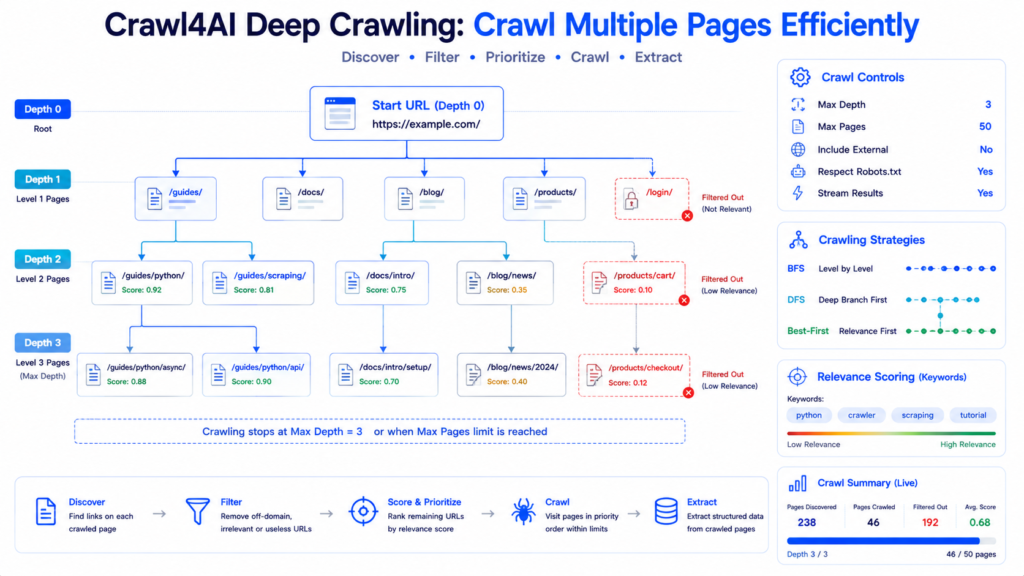
Crawl4AI deep crawling lets developers move beyond extracting a single URL and systematically explore linked pages across a website. A
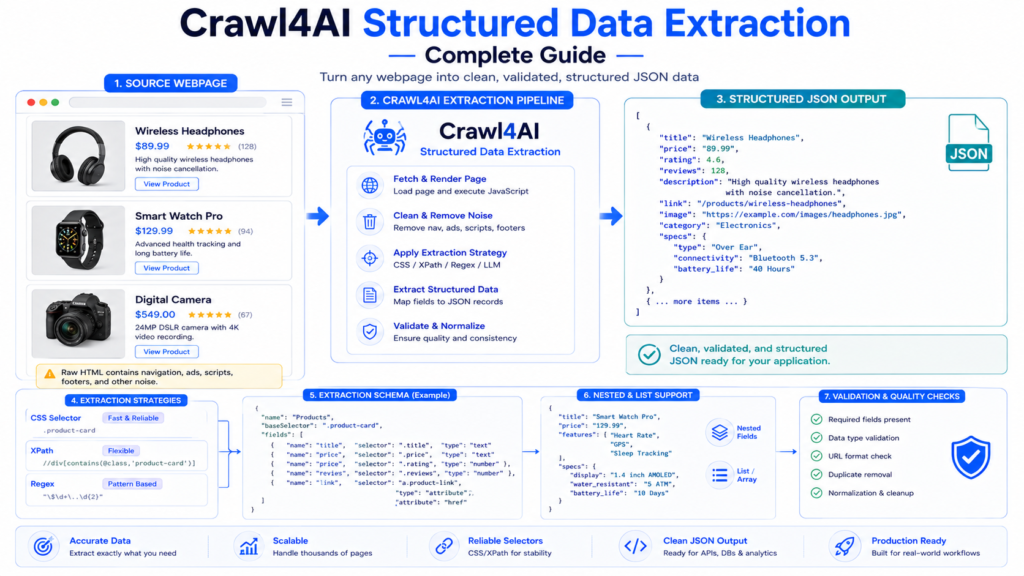
Crawl4AI structured data extraction turns webpage elements into predictable records that applications can process directly. Instead of returning an entire
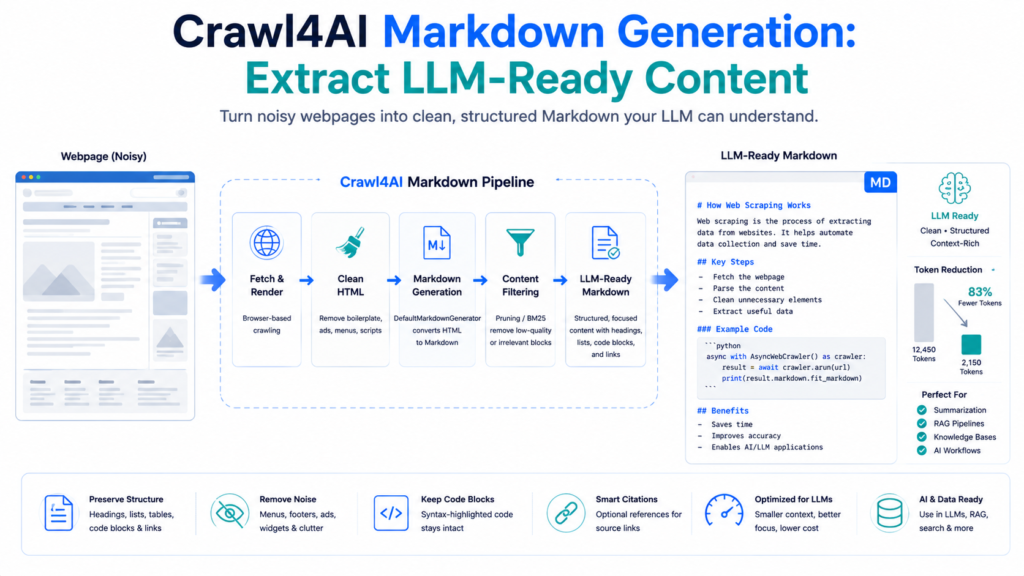
Crawl4AI Markdown generation converts complex webpage HTML into structured, readable content that is easier to use in LLMs, knowledge bases,
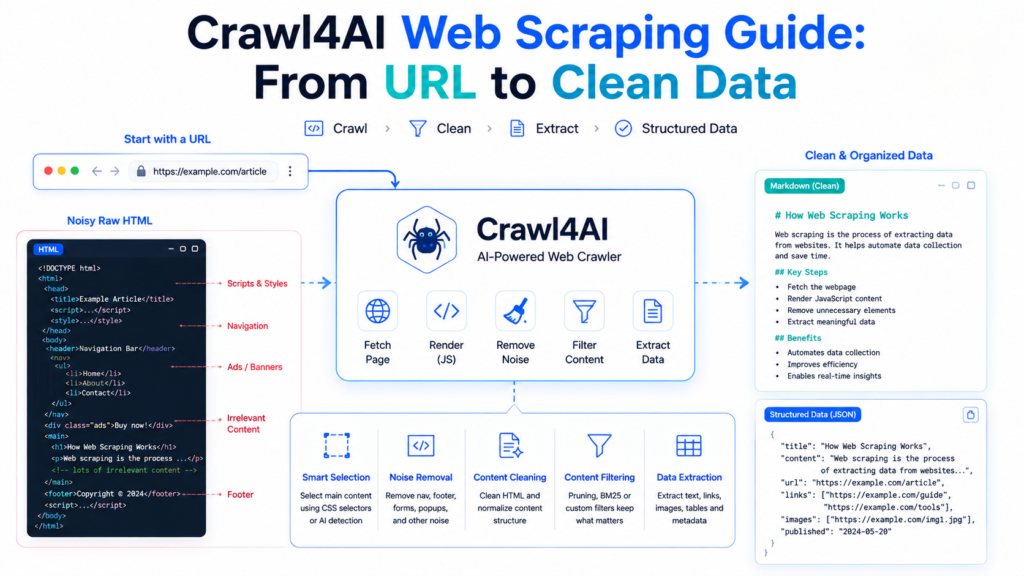
Crawl4AI turns a webpage URL into cleaner, more useful data by combining browser-based crawling with content selection, HTML cleanup, Markdown
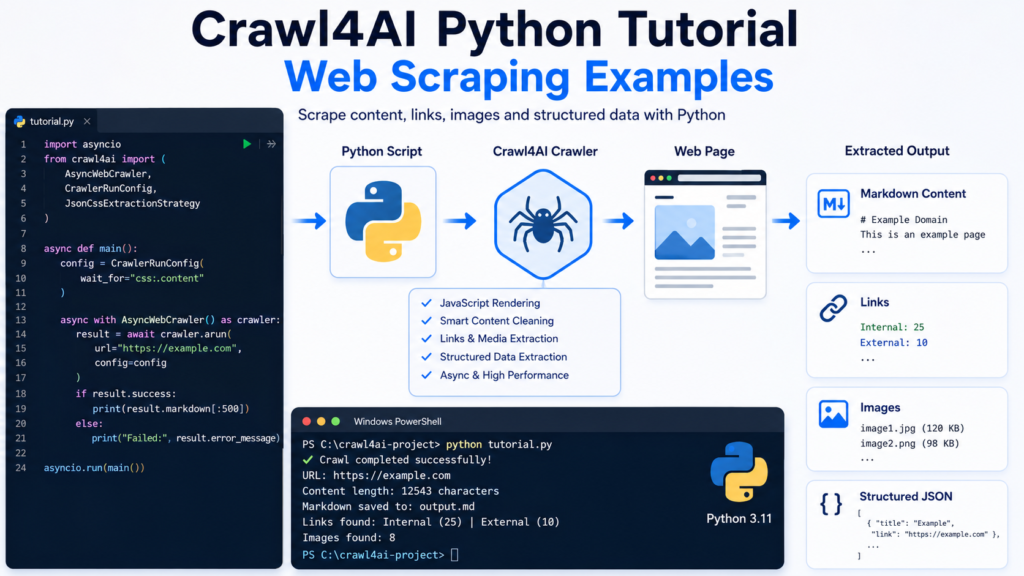
Crawl4AI gives Python developers a practical way to turn webpages into usable content without manually handling every browser, parsing, and
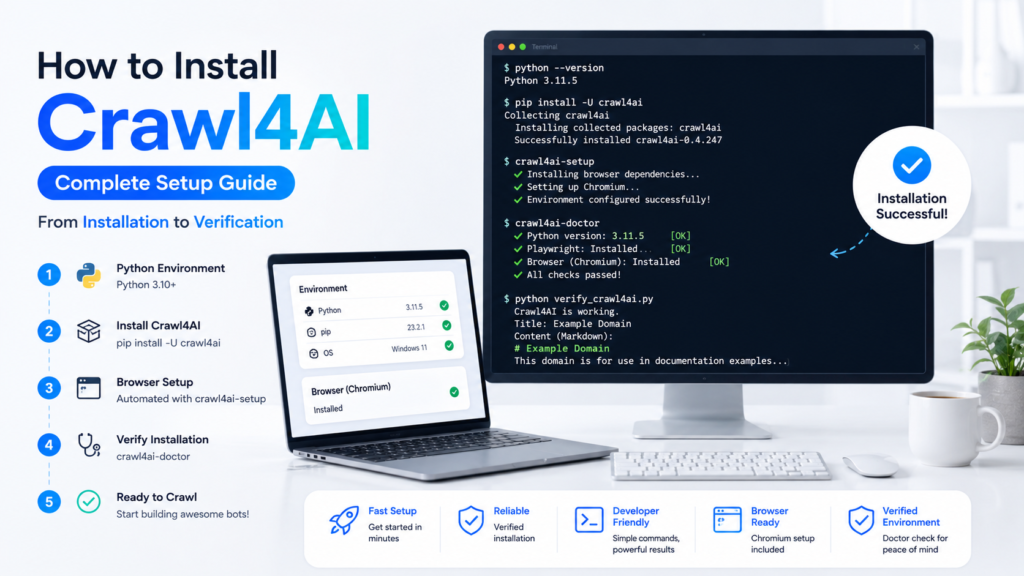
Crawl4AI installation starts with a compatible Python environment, followed by the package installation and browser setup required for web crawling.
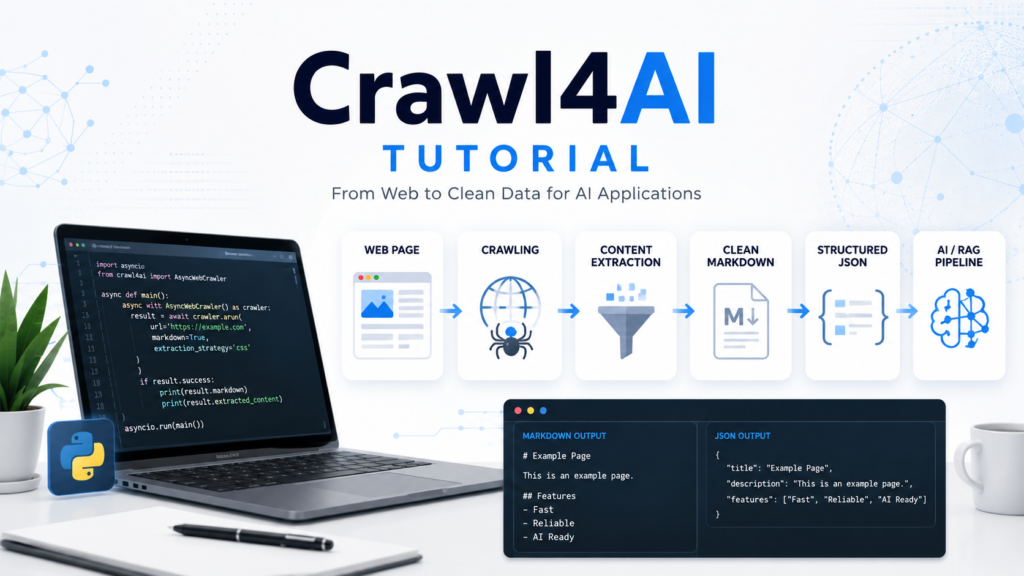
Crawl4AI gives developers a practical way to crawl webpages and convert web content into clean Markdown, structured data, links, media,